
Advanced Web Scraping for SEO and Competitor Intelligence: Overcoming Anti-Bot Protocols at Scale
Introduction
In modern Search Engine Optimization (SEO) and market intelligence, competitive data collection is critical. Whether monitoring real-time SERP rankings, auditing backlink footprints across millions of URLs, tracking dynamic e-commerce pricing, or analyzing content structures for programmatic SEO, automated data pipelines provide the foundation for actionable strategies.
However, target websites and search engines have deployed advanced anti-bot platforms (such as Cloudflare, Akamai, Imperva, and Kasada) to protect their public assets. Modern scraping blocks extend far beyond basic IP rate-limiting, leveraging advanced TLS fingerprinting, client-side JavaScript challenges, and automated behavioral analysis.
When scraping requests are blocked, data flows halt, rank-tracking metrics fail, and marketing decisions are delayed. This technical guide explores practical methods for optimizing data collection infrastructure, bypassing advanced bot detection, and building resilient web scraping pipelines.
How Modern Anti-Bot Systems Detect Crawlers
To design scrapers capable of scale, data engineers must understand how security systems evaluate incoming HTTP/HTTPS traffic. Modern verification checks rely on four main layers:
1. TLS Fingerprinting (JA3 / JA4 Signatures)
Before an HTTP request is evaluated, the server checks the TLS handshake. Standard HTTP request libraries (such as Python requests, urllib, or standard cURL) negotiate TLS handshakes using distinct configurations compared to real browsers (e.g., Google Chrome or Mozilla Firefox). Security systems map these JA3/JA4 signatures to immediately drop automated library requests.
2. Network Origin & IP Reputation
Target platforms cross-reference incoming IP addresses against global threat databases. Requests originating from public cloud providers (e.g., AWS, DigitalOcean, GCP) are flagged as suspicious by default, triggering high CAPTCHA challenge rates.
3. Client Environment Probing
Modern anti-bot systems inject client-side JavaScript challenges into responses. These scripts inspect browser context variables—such as navigator.webdriver, WebGL vendor flags, window dimensions, and mouse movement event listeners—to confirm whether the client is a headless process.
Practical Strategies for Building Resilient Data Pipelines
Strategy 1: Implement Protocol and Fingerprint Emulation
Aligning HTTP headers with network handshakes is essential for bypassing edge firewall rules.
·Align TLS Handshakes: Use specialized HTTP client tools (such as curl_cffi in Python or Go-based request engines) that actively mimic the TLS signature of target browser versions.
·Normalize Header Structures: Ensure standard browser header groups (User-Agent, Accept, Accept-Language, Sec-Ch-Ua, Sec-Fetch-Mode) are correctly ordered and match the emulated browser architecture.
Strategy 2: Utilize Dynamic Residential Gateway Routing
Data center IP connections are rarely sufficient for large-scale SERP monitoring or high-frequency page extraction. Search engines and major platforms monitor request volume per IP closely.
Python
# Example: Python request setup with TLS spoofing and dynamic residential gateway routing from curl_cffi import requests# Configure residential gateway tunnel credentials gateway_endpoint = "http://username:password@gate.niuproxy.com:8000"
proxies = { "http": gateway_endpoint, "https": gateway_endpoint }
headers = { "User-Agent": "Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/124.0.0.0 Safari/537.36", "Accept-Language": "en-US,en;q=0.9", "Sec-Ch-Ua": '"Chromium";v="124", "Google Chrome";v="124", "Not-A.Brand";v="99"', "Sec-Ch-Ua-Mobile": "?0", "Sec-Ch-Ua-Platform": '"Windows"', }
def scrape_target_page(url): try: # Impersonate legitimate Chrome browser TLS fingerprint response = requests.get( url, headers=headers, proxies=proxies, impersonate="chrome124", timeout=15 ) if response.status_code == 200: return response.text print(f"Request status flag: {response.status_code}") except Exception as err: print(f"Connection failure encountered: {err}")
·Per-Request Rotation for SERP Scraping: For high-volume keyword rank tracking, set up IP rotation so each request originates from a fresh address.
·Leverage Clean Residential IP Infrastructure: Utilizing high-quality network routing is critical. Solutions like NiuProxy offer access to large global residential IP pools that maintain high trust scores across major web targets, helping scrapers bypass rate limits and IP bans.
·Sticky Sessions for Multi-Step Workflows: For multi-page extraction that relies on session state or account logins, assign sticky sessions to preserve the same IP throughout the sequence.
When these data pipelines support a wider Telegram workflow, the gateway layer and the Telegram automation layer are better kept separate. Telegram Expert can handle Telegram-side operations such as multi-account management, searching chats and channels, audience collection, and other repeatable tasks, while NiuProxy provides the residential routing used by the surrounding data or account infrastructure.
Strategy 3: Hybrid Rendering Architecture
Full headless browser execution (using tools like Puppeteer, Playwright, or Selenium) consumes high CPU and memory resources.
·Stage 1 (HTTP Requests First): Run lightweight HTTP GET requests using TLS impersonation and residential gateways. This handles 80%+ of standard web pages quickly.
·Stage 2 (Headless Fallback): Route requests through headless stealth browsers only when client-side JavaScript execution or interactive challenge rendering is strictly required.
Technical Optimization Matrix
Operational Challenge | Root Cause | Technical Mitigation |
|---|---|---|
HTTP 429 / Rate Limit Errors | Exceeding request thresholds from a single IP address. | Route traffic through NiuProxy dynamic residential IP pools. |
HTTP 403 / Cloudflare Block Pages | TLS signature mismatch (JA3 flag) or data center IP classification. | Use TLS fingerprint impersonation (curl_cffi) paired with residential ISP IPs. |
CAPTCHA / Challenge Injection | Missing browser context flags or suspicious request patterns. | Deploy stealth headless browser instances with randomized humanized interactions. |
Incomplete DOM / JS Missing Data | Target content is rendered dynamically via client-side frameworks. | Transition request route from standard GET requests to a headless rendering framework. |
For teams that turn SEO or competitor intelligence into Telegram marketing workflows, Telegram Soft Expert can help centralize account operations and repetitive Telegram tasks once the research data is ready. This keeps data collection, routing infrastructure, and Telegram execution as distinct layers instead of forcing one tool to handle the entire stack.
Conclusion
Building scalable web scraping infrastructure for SEO and market analysis requires a multi-layered approach. By combining TLS fingerprint emulation, efficient hybrid rendering, and reliable residential network routing from providers like NiuProxy, data teams can maintain continuous extraction pipelines, avoid IP blocks, and gather the competitive intelligence needed to drive growth.
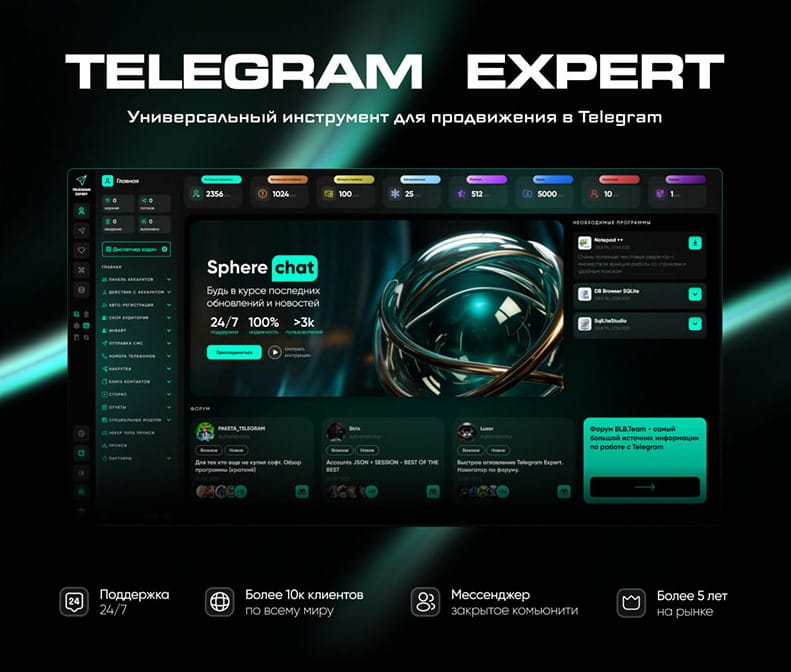
Download Telegram Expert - software for Telegram promotion
Telegram Expert is professional software for fast channel growth and sales in Telegram. Launch mass mailings and invites, warm up accounts without bans, consolidate dialogs in one place, and scale your team. All in one window - fast, safe, and tailored to your tasks.
What it can do:
- TDATA Converter - массово переводит session+json в TDATA.
- Booster - account warm-up via smart dialogs to increase trust.
- Registrar - account creation via any SMS services with the sms-activate standard.
- Duplicator - a second session for existing accounts for transfer and protection.
- Forwarder - routes incoming replies to a working group and sends replies to clients.
- Interceptor - catches messages by keywords from chats/channels and forwards them to you.
- Invite via admin - invitations even to restricted groups.
- Channel and chat cloner - full copies, including protected content.
- Reporter - mass complaints about messages/users/channels.
No one has left a comment yet
How to Manage Multiple Telegram Accounts: Tools and Best Practices
Preview: Running multiple Telegram accounts for marketing? This guide covers what Telegram's anti-spam system actually detects, how to choose the right gateway type, and a step-by-step warm-up schedule that keeps your accounts alive long-term. Running multiple Telegram accounts is standard practice for any serious marketing operation. You need separate accounts for different campaigns, client projects, geographic regions, or A/B testing message strategies. A single account simply can't cover ...

Telegram via IP infrastructure: Q&A with the Astro team
[media mw=100]3386[/media] Astro provides access to web data through residential, mobile, and datacenter IP relays. The team broke down what matters when working with Telegram: choosing the IP type; connecting over SOCKS5; IP-change modes; running multiple accounts. Free test and bonuses Free test – $3 to your balance after registration. Discounts up to 25% and special corporate terms apply, as well as a referral program. Key infrastructure facts...
Competitor Analysis on Telegram: How to Scrape Data Without Hitting the Limits
Telegram has long outgrown its role as "just a messenger" — for many niches, it's the primary channel for reaching an audience: channels, chats, bots, mini-apps. And wherever there's an audience, there's competition. Marketers, SMM specialists, and product teams increasingly keep an eye not only on their own channels but on their competitors' as well: how many subscribers they have, how often they post, how strong their engagement is, and which topics resonate most. It sounds simple enough — ...
How AI Agents Use Network Intermediaries for Reliable Web Data Collection in 2026 | Gateproxies
AI DATA INFRASTRUCTURE GUIDE AI agents can search, compare, monitor, and summarize public web information faster than a manual research team. Their output is only as reliable as the data pipeline beneath them. IP routing infrastructure matters when that pipeline needs geographic coverage, repeatable sessions, parallel collection, and clean separation between requests. 2026 trend guide Practical infrastructure 7 original visuals [me...